// Josh Smith
Gallery

// SMITH, JOSHUA: DATA_SCIENCE_

>

Data
Science

[MINOR]
PROJECT 01 / 04
Data Mining: Prediction & Classification

> /DATA-SCIENCE

Data Mining: Prediction & Classification

R assignment building prediction and classification models for property valuation and wheat variety identification, using linear regression, decision trees, and random forests.

STACK
  • R
  • tidymodels
  • rpart.plot
COURSE
  • Data Mining
View on GitHub

// Features08 ITEMS

  • Property price prediction via linear regression, stepwise AIC reduction, decision tree, and random forest
  • RMSE comparison across all four models to select the best predictor
  • Wheat variety classification across three varieties (Canadian, Kama, Rosa)
  • LDA assumption checking: multicollinearity, multivariate normality, and homogeneity of covariance
  • ROC curve comparison across LDA, two decision tree variants, and random forest
  • Outlier detection and removal via ggpairs and jitter facet plots
  • Decision tree visualised with rpart.plot to extract key differentiating splits
  • Final CSVs exported with .pred / .pred_class columns appended to test data

// Challenges03 LOGGED

CHALLENGE 01

PROBLEM
LDA assumptions failed on wheat data despite visually linear class separation
SOLUTION
Multicollinearity in size features (length, width, perimeter) and heterogeneous covariances ruled out LDA, multinomial logistic, and Naive Bayes. random forest used instead

CHALLENGE 02

PROBLEM
Rushed straight into modelling without exploratory analysis on the property dataset
SOLUTION
Iterated across four model types and compared RMSE empirically; random forest won with lowest training RMSE

CHALLENGE 03

PROBLEM
Namespace conflict between stats::step and tidymodels step functions
SOLUTION
Resolved with explicit stats:: namespace prefix, mirroring C++ scope resolution
PROJECT 02 / 04

> /DATA-SCIENCE

Football Analytics: PL vs La Liga

Group data science project scraping 3 seasons of team statistics from FBref across the Premier League and La Liga, using regression and classification models to analyse and predict team performance metrics.

STACK
  • Python
  • Selenium
  • BeautifulSoup
  • pandas
COURSE
  • Data Wrangling and ML
View on GitHub

// Features08 ITEMS

  • Selenium + BeautifulSoup scraper pulling 6 stat categories (keeper, shooting, passing, shot creation, possession, playtime) across 3 seasons from FBref
  • Data pipeline: column renaming, one-hot encoding, multi-season concatenation, and CSV export for reproducibility
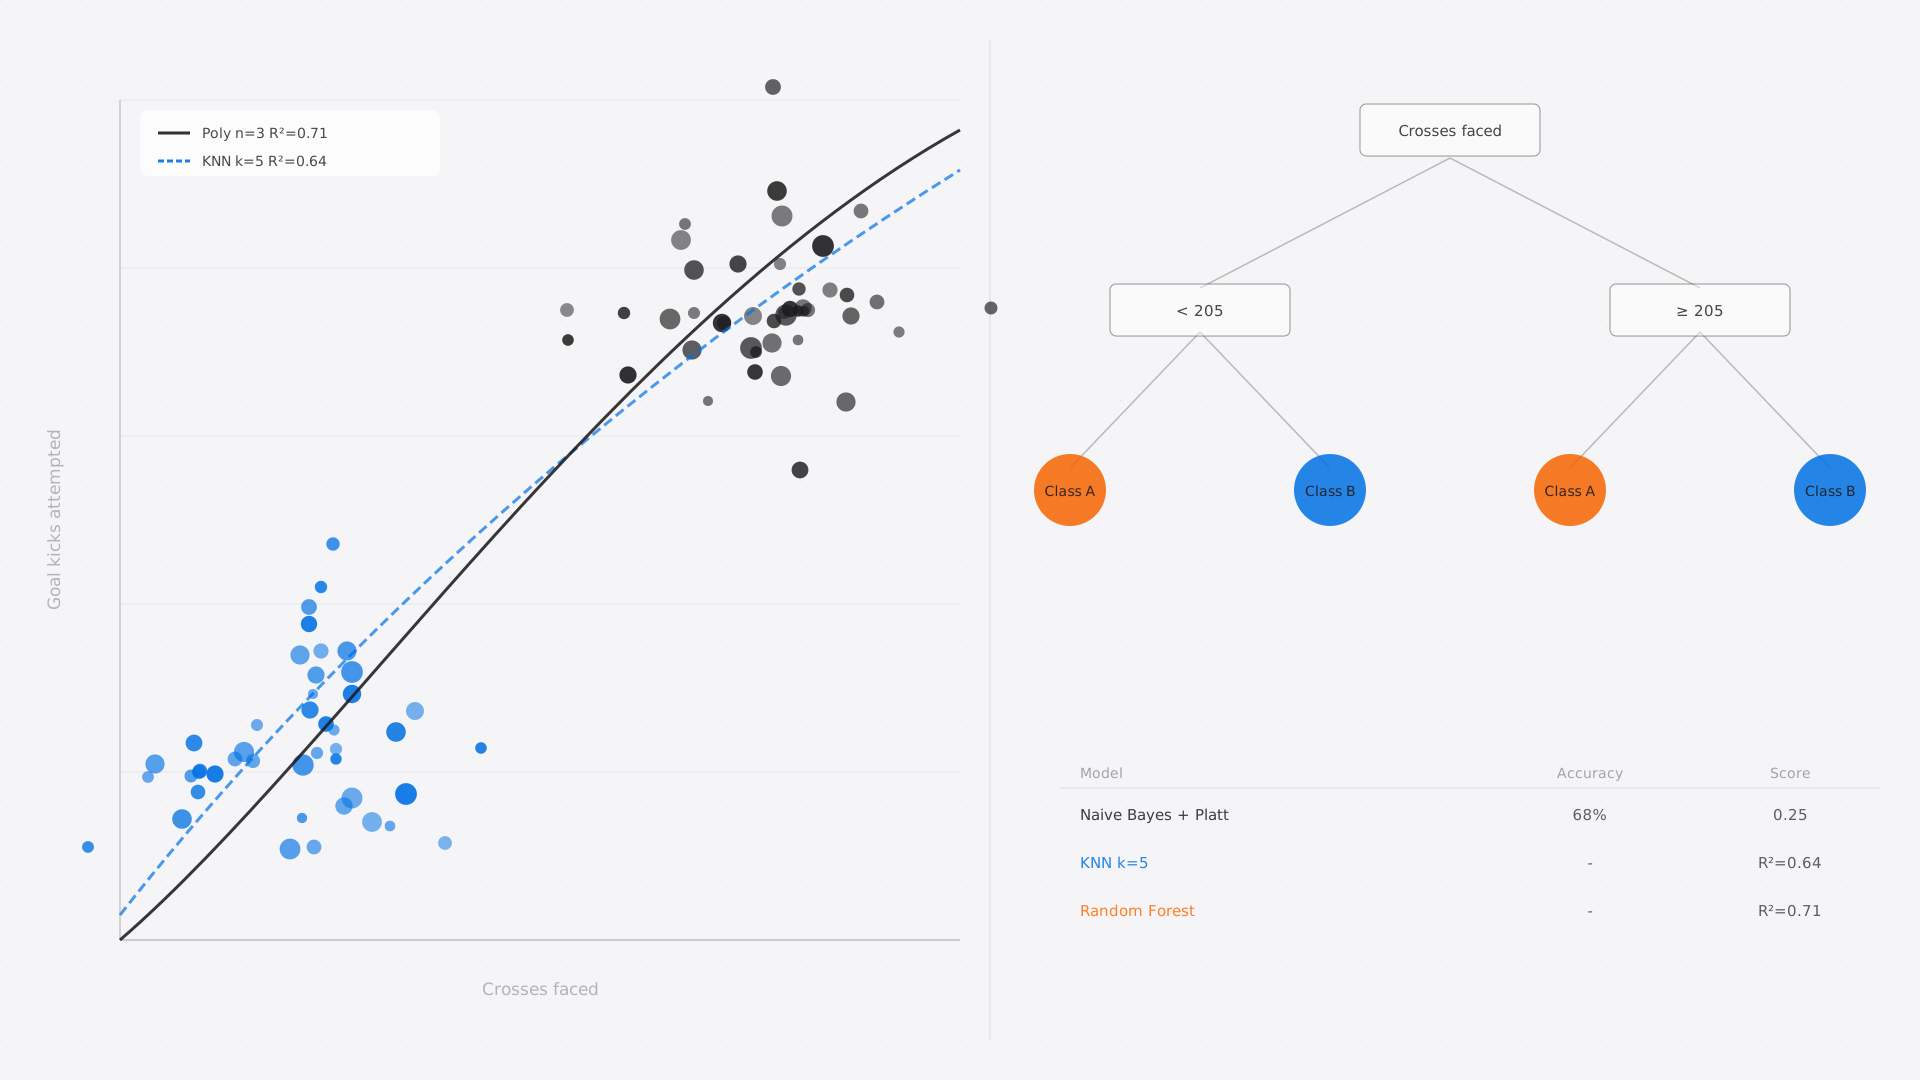
  • Polynomial regression (n=1-3) with residual analysis to predict goalkeeper kick attempts from crosses faced
  • Naive Bayes league classifier with Stratified k-Fold CV and Platt Scaling calibration. Reducing overconfidence in predicted probabilities
  • KNN regressor vs linear/polynomial regression comparison with R² and RMSE sweep across k values
  • Random Forest classifier and regressor benchmarked against polynomial and KNN models
  • OLS regression on shooting data: shots on target and distance explain 82% of goal variance
  • Three-way classification comparison (Logistic Regression, Random Forest, Naive Bayes) on possession and playtime features. Playtime features achieved 96% accuracy with Logistic Regression

// Challenges03 LOGGED

CHALLENGE 01

PROBLEM
FBref renders tables dynamically, requests alone returned empty pages
SOLUTION
Switched to headless Selenium with a 5-second render wait before passing the page source to BeautifulSoup

CHALLENGE 02

PROBLEM
Naive Bayes overconfident at probability extremes (over-predicting below 0.4, under-predicting around 0.5 and 0.8)
SOLUTION
Applied Platt Scaling via logistic regression on log-odds, aligning predicted probabilities with true class frequencies and lowering Brier score

CHALLENGE 03

PROBLEM
A numeric column consistently returned NaN on pd.to_numeric despite appearing valid
SOLUTION
Diagnosed as hidden whitespace; stripped and dropped the column since it contained no discriminating information
PROJECT 03 / 04
AdaBoost meets Kaggle: Loan Default Prediction

> /DATA-SCIENCE

AdaBoost meets Kaggle: Loan Default Prediction

From-scratch AdaBoost with decision stumps in Python for an in-class Kaggle competition predicting loan defaults, with margin analysis, ensemble pruning, and an XGBoost comparison trained on AWS SageMaker.

STACK
  • Python
  • XGBoost
  • AWS SageMaker
  • Amazon S3
COURSE
  • Applied Machine Learning and Big Data Processing
View on GitHub

// Features08 ITEMS

  • AdaBoost implemented from class code: weighted decision stumps, alpha weighting, and sample re-weighting each round
  • Best Kaggle score of 0.916 AUC, placing 7th in class
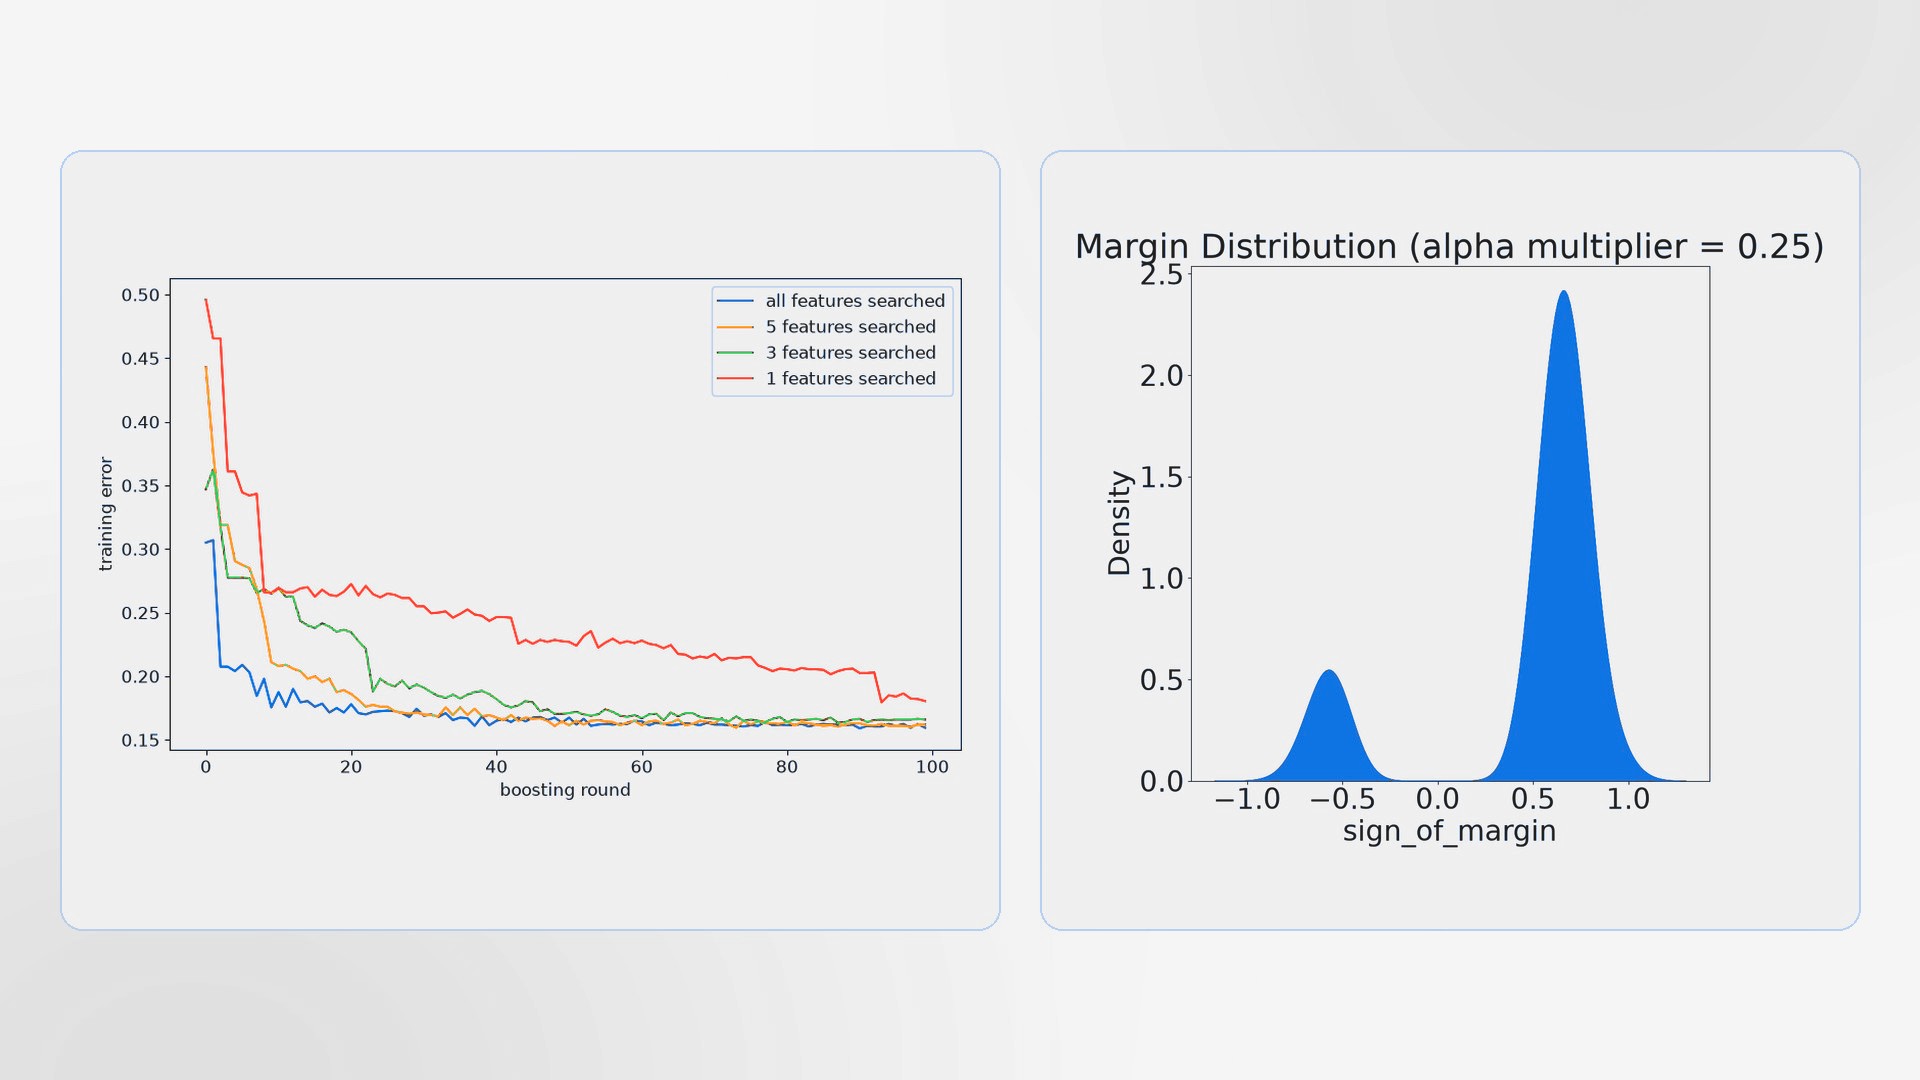
  • Margin distribution analysis: sign = correct vs misclassified, magnitude = ensemble confidence
  • Alpha-multiplier experiments (0.05 to 2) tracking effective sample size, features used, and train/test error
  • Threshold analysis of precision vs recall (0.70 / 0.41 at the default threshold) framed around the cost of a missed default
  • Engineered features such as interest_burden and cred_hist_by_age, tested with feature-subset experiments
  • Post-training pruning by alpha rank, measuring test error as the kept ensemble grows from 5 to 100 stumps
  • XGBoost baseline trained via SageMaker estimator/transformer with data in S3 and IAM-scoped access

// Challenges03 LOGGED

CHALLENGE 01

PROBLEM
Pruning results flipped between a 200-sample and a 1,000-sample training set
SOLUTION
Re-ran on the larger balanced sample; the curve behaved as expected, showing small evaluation sets give unreliable conclusions

CHALLENGE 02

PROBLEM
Ranking stumps by alpha made a poor pruning strategy
SOLUTION
Diagnosed that alpha measures a stump on its own round, not whether it adds anything new, so the top stumps were likely near-duplicates

CHALLENGE 03

PROBLEM
Test error plateaued around 0.16 to 0.18 regardless of tuning
SOLUTION
Experiments showed it only improved with more training data; scoring on AUC instead of hard labels gave the best Kaggle result
PROJECT 04 / 04
Gradient Boosting meets NZ Inflation

> /DATA-SCIENCE

Gradient Boosting meets NZ Inflation

From-scratch gradient boosting in Python forecasting New Zealand CPI inflation, with custom loss functions, learning-rate schedules, early stopping, and an expanding-window backtest against XGBoost, LightGBM, CatBoost and scikit-learn.

STACK
  • Python
  • scikit-learn
  • XGBoost
  • LightGBM
  • CatBoost
COURSE
  • Applied Machine Learning and Big Data Processing
View on GitHub

// Features08 ITEMS

  • Gradient boosting implemented from class code: split search, residuals, stump training, and prediction updates
  • MSE, MAE and Huber losses compared: MAE generalised best (test MSE 2.67 vs 3.59 for MSE)
  • Stump vs linear weak learners across step sizes 0.1 to 0.75
  • Constant, inverse, and exponential learning-rate decay schedules
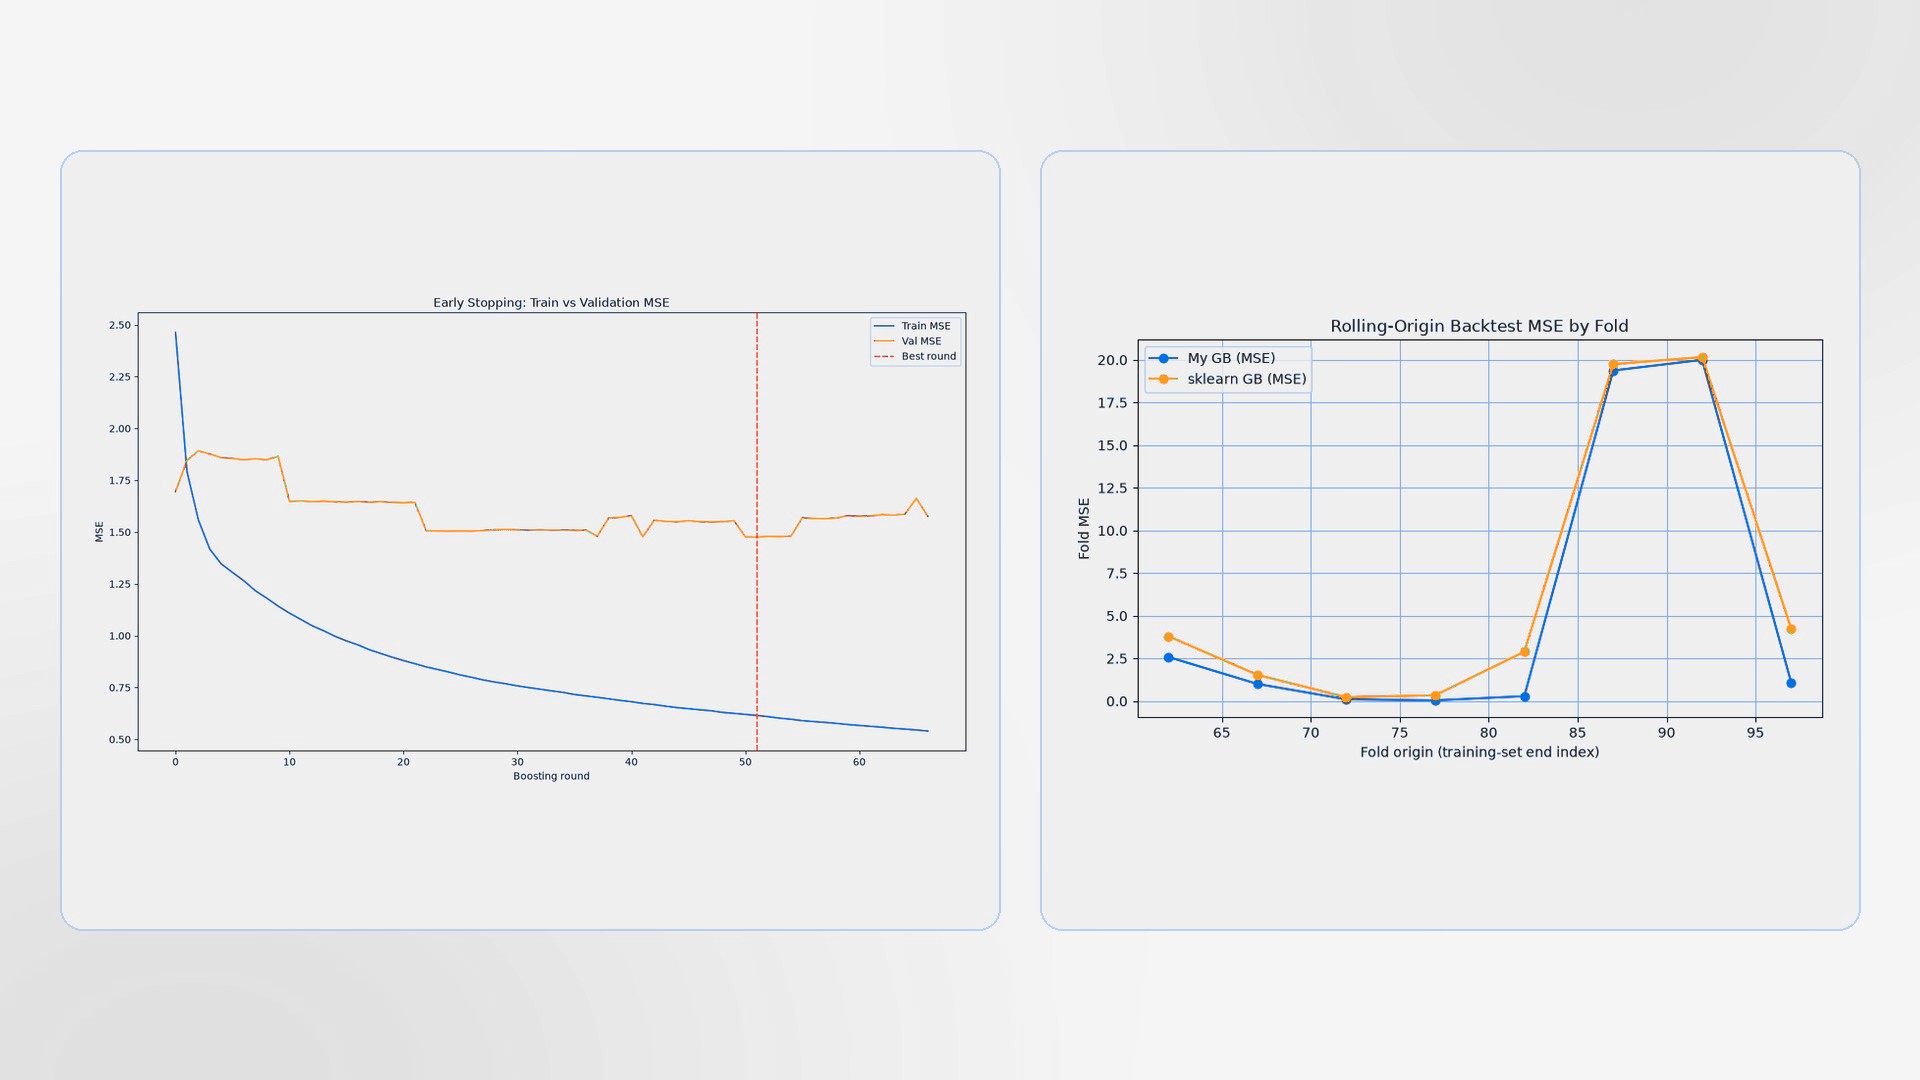
  • Validation-based early stopping with patience, best round 51 of 67
  • External RBNZ series (trade-weighted index, mortgage rate) plus 14 engineered CPI features: rolling sums/means, slopes, and lags
  • Expanding-window backtest over 8 folds, cross-checked fold by fold against scikit-learn
  • At matched hyperparameters my GB beat XGBoost, LightGBM, CatBoost and scikit-learn (MSE 3.39 vs 3.92 to 7.98)

// Challenges03 LOGGED

CHALLENGE 01

PROBLEM
External series and rolling features risked leaking future information into each prediction
SOLUTION
Shifted every external series by one period after aligning to the target index, so no feature uses data from a later period

CHALLENGE 02

PROBLEM
Proving the expanding-window backtest was correct, not an artefact of my implementation
SOLUTION
Ran a matched scikit-learn model through the same function; both spiked on the same folds, confirming the windowing logic

CHALLENGE 03

PROBLEM
Flexible stump learners kept improving training fit while test error stalled
SOLUTION
Switched to a linear weak learner with an inverse-decay learning rate, cutting competition MSE from 3.91 (stumps) to 1.74